Recurring operational problems are rarely caused by one weak person or one broken step. They persist because targets, delays, incentives and workarounds interact as a system. In African operations—where infrastructure constraints, variable demand and limited buffers often amplify disruption—local fixes can quietly move risk elsewhere.
The pattern behind repeat failures
Consider a service team measured mainly on daily output. When demand rises, managers shorten quality checks to protect throughput. Errors appear later, rework increases and experienced staff are pulled away from normal work. Capacity falls further, creating pressure for even faster processing. What looked like a productivity solution has become a reinforcing feedback loop.
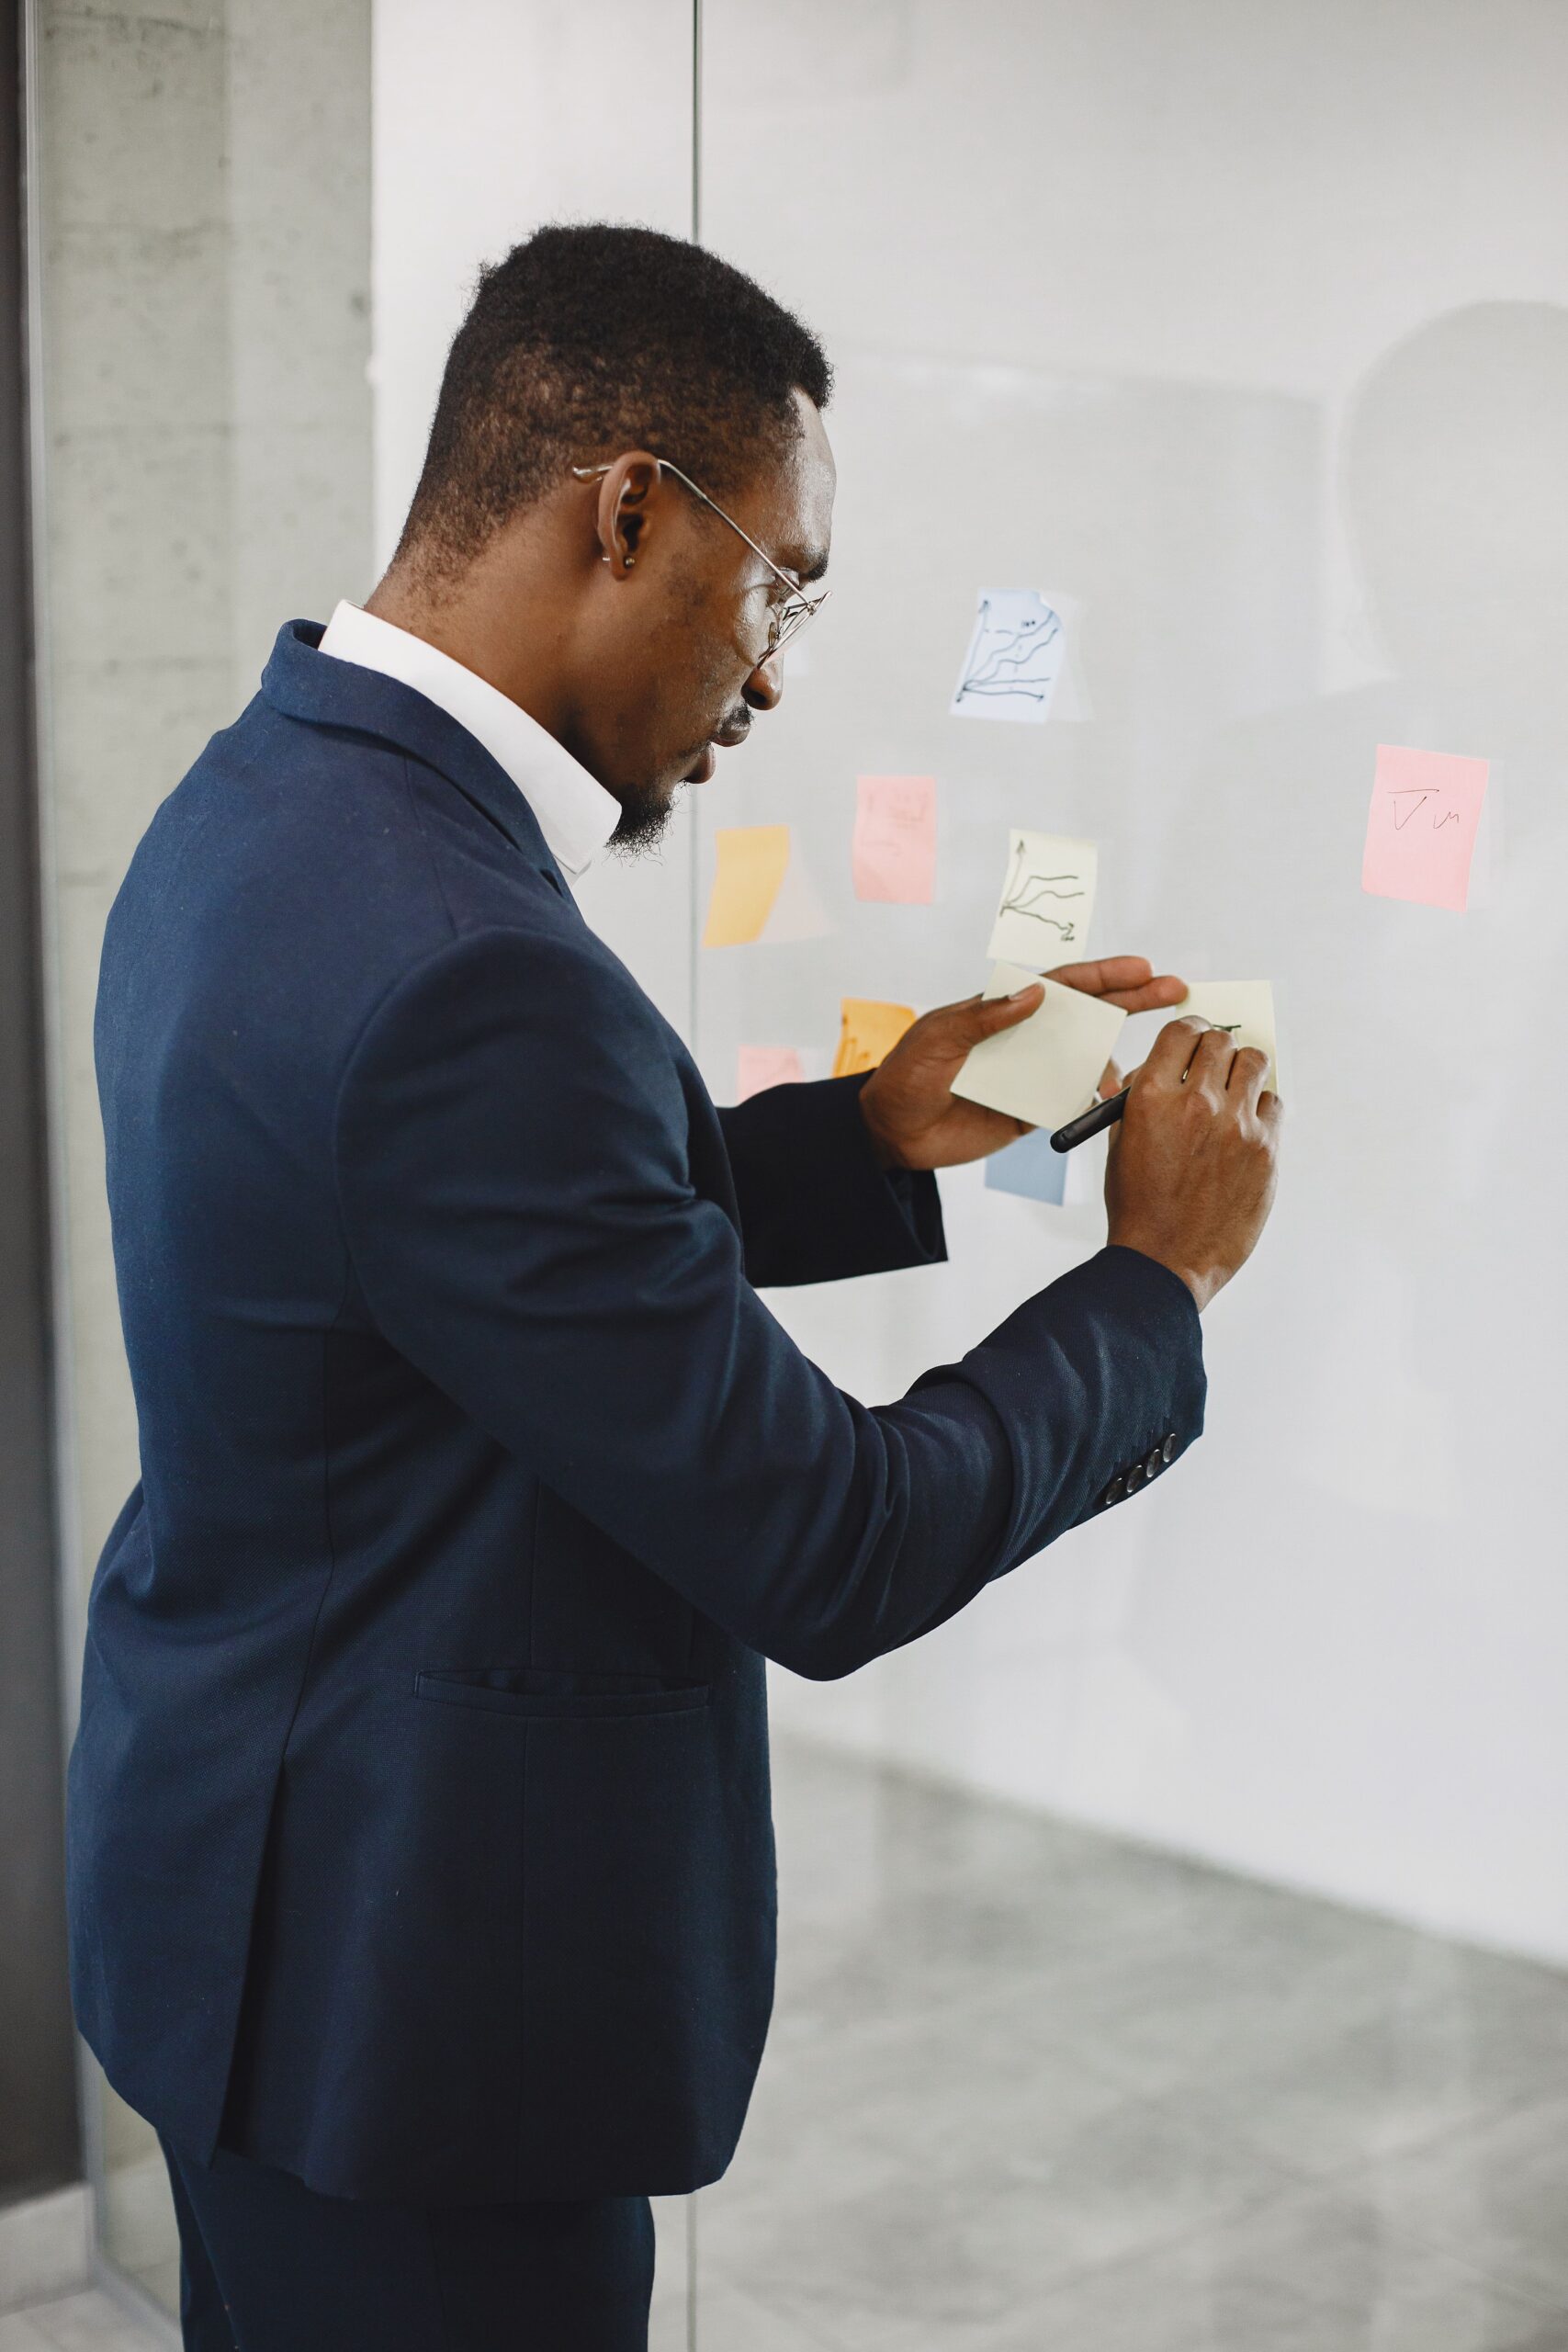
Map causes and feedback—not blame
Begin with one recurring outcome: missed delivery, repeat defects, excessive escalation or customer abandonment. Ask what conditions increase it, what consequences follow and where time delays hide the relationship between action and result. Include policy, technology, workload, skills, supplier behaviour and customer response.
This wider view complements end-to-end process re-engineering. A process map shows how work should flow; a feedback map explains why the organisation repeatedly returns to the same failure pattern.
Choose a leverage point
The most visible symptom is not always the best place to intervene. Adding inventory may reduce today’s stockout while weakening demand discipline. Adding approvals may reduce one control failure while increasing queues and informal bypasses. More reporting may create data without improving decisions.
A stronger intervention changes the conditions that generate behaviour. Examples include aligning measures across functions, moving control closer to the source, reducing information delay, clarifying decision rights or redesigning a high-risk interface. The same principle underpins effective systems-engineering interface management.
Run a 30-day learning cycle
Select one leverage point and define the expected system response. Track a small set of measures covering the intended benefit and likely side effects: throughput and rework, service and inventory, control quality and lead time. Review the evidence through a disciplined daily management rhythm, then adapt before scaling.
Begin with a problem that has survived several improvement attempts. If the same pattern returns under pressure, the system is signalling that its governing conditions—not merely its visible symptoms—must change.
Systems thinking does not make decisions abstract. It makes them more practical by exposing relationships that conventional problem-solving misses. Agile Ops helps organisations translate those relationships into focused interventions, measurable learning and stronger whole-system performance.